
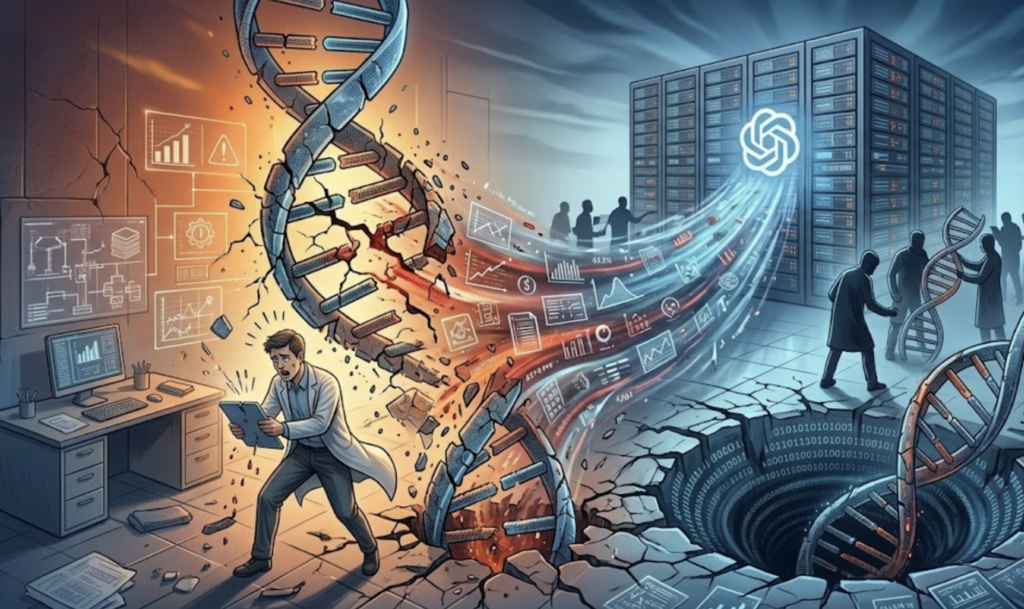
There is a moment that any researcher using public AI for their work should pause and examine — not the moment they paste sensitive data into a chat interface, but the moment just before it, when they look at the screen and prepare to press Enter. In that moment, the question that should be asked is not ‘will the AI give me a useful answer’ but rather ‘where does this data go after I send it, who can access it, and what happens to it from that point forward.’
That question is rarely asked. And the silence is accumulating consequences.
Over the past three years, the academic community has witnessed a wave of AI adoption in research workflows that has substantially outpaced the development of principled thinking about the risks involved. Scholars discuss unpublished peer review processes in documents they attach to ChatGPT for writing assistance. Graduate researchers paste raw interview transcripts — including participant names, geographic identifiers, and sensitive personal disclosures — into public AI platforms for thematic analysis. Health researchers share incompletely anonymized clinical data with commercial models to identify patterns. None of these people have malicious intent. Many of them do not realize they may have violated the ethical commitments they signed with their institutional review board.
⚠ Every time you paste research data into a public AI platform, you are performing a data transfer that may be irreversible — regardless of how harmless the interface appears.
I. What Actually Happens When You Send Data to a Public AI
Most users do not read terms of service. That is the understood reality of the digital era. But for researchers working with sensitive data, failing to read those terms is not a minor inconvenience — it is a significant ethical and legal exposure.
To understand why, it is necessary to distinguish three different categories of risk that most discussions of ‘AI and privacy’ collapse into one. Storage risk is the possibility that data you submit is retained on the provider’s servers, where it may be accessible to their employees, subject to legal process, or exposed in the event of a security breach. Training risk is the possibility that your data is used to improve future versions of the model, which in principle means that information you submit could re-emerge in responses to other users in some transformed form. Inference risk is the most subtle: even if your data is never stored or trained on, the mere fact that you queried with it — what kind of queries you made, when, from what IP address — creates metadata that can reveal sensitive information about your research project.
OpenAI, Anthropic, Google, and other major providers have substantially improved their privacy policies since the early days of public AI deployment. Many now offer enterprise tiers with stronger security commitments and explicit contractual protections around data use for training. But even with those improvements, there is one guarantee that no public AI privacy policy can provide: that your data never leaves an environment you control. Because by definition, the moment you send data to someone else’s server, you have relinquished that control.
II. What Counts as Sensitive Research Data — The Categories Researchers Miss
A significant source of risky behavior is ambiguity about what constitutes sensitive data in the context of academic research. Many researchers have a correct intuitive understanding that social security numbers and medical records require protection, but have less well-developed intuitions about the categories of sensitivity that arise specifically in research contexts.
Interview and focus group data represents the first important category. Even when transcripts have been anonymized — names replaced with codes, locations obscured — a sophisticated AI model can potentially infer identities from the combination of professional details, political views, and specific experiences described within the interview. This is particularly true in small communities where a small number of identifying characteristics is sufficient to identify an individual. The test is simple: if a human reader familiar with the community could identify the speaker from the transcript, a model trained on data from that community may be capable of the same inference.
Unpublished research data represents a different category of sensitivity that is frequently overlooked. Preliminary findings from funded research, results from ongoing clinical trials, manuscripts prior to peer review — these are often controlled by grant agreements, research ethics protocols, or non-disclosure agreements with industry partners. When that data is shared with commercial AI platforms, the researcher may be in violation of those agreements even if the data is never incorporated into model training. The legal exposure is independent of the AI provider’s actual data practices.
Politically sensitive research topics constitute a third category. Researchers working on secessionist movements, minority organizing, government criticism in high-censorship environments, or whistleblowing in powerful institutions need to recognize that the metadata of their queries — what topics they research, what documents they analyze, what sources they reference — may itself be sensitive even when individual content pieces are not. No public AI company’s terms of service offer adequate protection in this context, because these companies are subject to legal process in multiple jurisdictions and may be compelled to disclose user data under legal orders.
The problem is not whether the AI provider is trustworthy. The problem is that public AI infrastructure is designed to serve millions of users — not to protect a specific researcher’s data against their specific risks.
III. Academic Ethics in the AI Era: The Gap That Has Not Been Filled
Most existing research ethics frameworks — from the Belmont Report to the US Common Rule to European GDPR protocols — were written in a world where ‘data leaving the research facility’ meant physical files being transported in a secure vehicle. The digital reality of submitting data to an AI chat interface in seconds is something those frameworks have not yet caught up with.
This creates a legal and ethical grey zone in which researchers frequently find themselves. Institutional review boards typically approve data management protocols designed before public AI existed. Participant informed consent agreements typically do not mention that participant data may be processed by commercial AI models. This places researchers in the legally peculiar situation of potentially complying fully with the letter of their approved protocol while violating the spirit of the commitments their participants were given.
There are cases in which that violation has measurable legal consequences. The European General Data Protection Regulation imposes strict requirements on the transfer of EU citizens’ personal data to third parties — including AI providers. Submitting even partially anonymized EU participant data to a US-based AI company without an adequate Data Protection Framework mechanism in place is technically a GDPR violation — one that can carry fines of up to four percent of the organization’s annual global turnover, or twenty million euros, whichever is higher. No university wants to discover whether regulators are willing to apply that penalty to careless AI data entry.
The broader epistemological problem is that the pace of AI adoption in research has outrun the pace of ethical framework development by a substantial margin. Technology moves on the timescale of product releases. Academic ethics develops on the timescale of committee deliberation, professional association consensus, and regulatory revision. The gap between those two timescales is where the risk currently lives, and closing it requires deliberate choices by individual researchers rather than waiting for institutional guidance to catch up.
IV. The Architecture of the Solution: Why a Self-Hosted Gateway Changes Everything
Understanding the problem is one half of the solution. The other half is understanding what is technically possible and what is practically deployable in the context of an individual researcher or a small research group working with limited resources. The situation here is substantially better than it was three years ago.
Local large language models have undergone a quiet revolution. Models including Meta’s Llama 3.1, Mistral, Google’s Gemma, and Alibaba’s Qwen now offer performance on many research tasks sufficiently close to leading commercial models to serve as practical alternatives for a significant range of use cases — while running entirely on hardware the researcher controls. When a model runs locally, no data leaves the researcher’s machine. No third-party server receives a transmission. No terms of service govern what happens to the submitted text. The storage risk, training risk, and inference risk from the provider side are all eliminated by architecture rather than by trust.
But running a raw local model is not a complete solution for most research workflows. Without an orchestration layer — a gateway — practical use is limited by the absence of consistent prompt management, session history across documents, and the ability to share access across a research team in a controlled way. This is the function that OpenClaw Gateway fills.
OpenClaw Gateway sits between the researcher and the language model, whether that model is local or cloud-based. In fully local configuration, it coordinates communication between the user interface and a model running on the same machine or internal network, providing session management, conversation history, and controlled multi-user access — all without any data leaving the physical environment the researcher controls. This is architecturally distinct, not merely incrementally safer, from using ChatGPT Enterprise or Claude Team. Those products offer genuine security improvements over their consumer counterparts, but they still place data on someone else’s servers, subject to someone else’s policies and legal obligations.
V. The Risk Spectrum: A Framework for Deciding What Requires Self-Hosting
Self-hosting is not the right answer for every research situation. There are genuine trade-offs involved — in computational resources, in model performance on certain specialized tasks, and in setup time. The practical question is how to assess the risk profile of your specific project accurately enough to make an informed decision.
At one end of the spectrum sits low-sensitivity work: synthesizing findings from already-published literature, translating published academic texts, analyzing the grammar and style of manuscripts that contain no participant data, or generating generic interview questions. For these tasks, using public AI is reasonable and the risk-benefit ratio clearly favors the benefits.
At the other end sit situations that require self-hosting or at minimum private cloud deployment: processing participant data from vulnerable populations, analyzing documents protected by confidentiality agreements, working with patient data or medical histories even when partially anonymized, conducting interview research in politically sensitive environments, and handling proprietary data in industry partnership research. In these cases the appropriate default is self-hosted infrastructure, with public AI as an option only for clearly non-sensitive supporting tasks.
The difficult terrain is in the middle — and this is where the majority of real research projects actually fall. Anonymized data from large surveys, textual analysis from open sources combined with personal metadata, comparative policy research using unpublished government documents. For these cases, the correct decision requires careful assessment of the specific commitments made to participants, the legal requirements of the jurisdiction where the research is conducted, and the severity of harm that a disclosure incident would cause — not only to the researcher but to the people being studied.
VI. Practical Implementation: Building a Secure AI Environment for Research
For researchers who have concluded that their project requires local deployment, the setup process has become meaningfully more accessible than it was three years ago. It is no longer the exclusive territory of systems engineers, though some technical literacy remains necessary.
The first layer is selecting a model appropriate for the task and hardware. Meta’s Llama 3.1 70B in Q4 quantized form can run on a machine with a 24GB VRAM consumer GPU and delivers performance sufficient for most academic text-processing tasks. For less powerful hardware, Llama 3.1 8B or Mistral 7B offer strong performance at lower quantization levels. The crucial point is that these models can operate fully offline after download — no internet connection is required during inference, which means no transmission channel exists through which data can be inadvertently transmitted.
The second layer is deploying OpenClaw Gateway between the researcher and the model. In fully local configuration, the Gateway runs on the same machine or internal network, providing a consistent interface, session management, and the ability for multiple research team members to access the model without each requiring an individual setup. This means the principal investigator can configure the environment once and provide controlled access to team members — analogous to granting access to a secure research database.
The third layer, frequently overlooked, is documentation. Every AI-assisted research project should have a clear data protection statement in its IRB protocol specifying that AI processing occurs on researcher-controlled hardware, that no data is transmitted to external servers, and which model is being used. This is not only good compliance practice — it is protective evidence if questions about data handling arise after the fact, as they increasingly do in an era where funding agencies and journal editors are beginning to ask pointed questions about AI use in submitted work.
Conclusion: Convenience Is a Policy Choice
When researchers use public AI for sensitive research data, they are making a policy decision — even when they do not frame it as such. They are choosing that the convenience of immediate access to high-performance models outweighs the risks created by the security architecture of that infrastructure. This may be the right trade-off for many use cases. But it is a trade-off that should be made deliberately, with clear understanding of what is being exchanged, rather than by default.
The necessary shift is not to abandon AI in research — that would be a disproportionate response to the actual problem. The necessary shift is to abandon the assumption that convenience and safety are compatible in all contexts. Sometimes they are. Sometimes they are not. Researchers have a professional and ethical responsibility to know the difference.
Research participants share their data with academics because they have been assured it will be protected. That assurance does not end at the door of the research building. It extends to every small decision made about how that data is handled — including the decision to press Enter after pasting it into an AI chat interface.
◉ 0 Thảo luận Khoa học