
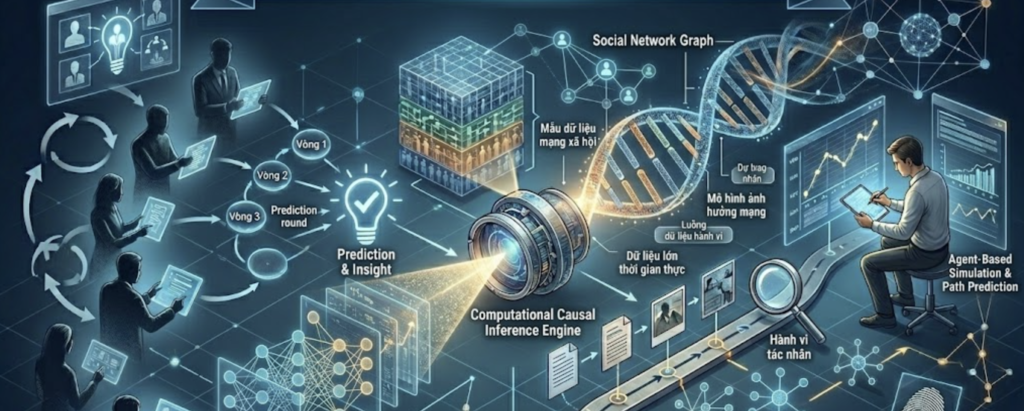
In 2009, David Lazer and colleagues published a visionary piece in Science titled simply ‘Computational Social Science.’ They argued that the explosion of digital data — from email, mobile phones, social networks, and geographic information systems — was creating a ‘new telescope’ for social research, capable of observing human behavior at scales and resolutions previously impossible with traditional methods. Fifteen years later, that vision has become reality — accompanied by challenges the original paper only partly anticipated.
Computational Social Science (CSS) is the academic field at the intersection of social science, statistics, and computer science. Not a replacement for traditional methods, CSS is an expansion of analytic capacity: the ability to process data at scales of millions and billions of observations, detect hidden patterns in text and networks, simulate complex social systems, and test social theories with unprecedented precision. It is also a field with distinctive risks: big data does not automatically mean good data, and algorithms do not automatically mean objectivity.
CSS does not replace the sociological or political science question. It changes the speed and scale at which those questions can be asked and answered.
PART 1: Three Intersecting Disciplines — Why CSS Requires All Three
From Social Science: CSS inherits meaningful questions — why do humans form coalitions, how does information spread, what conditions lead to collective action. Without social-theoretical foundations, a computer scientist may discover interesting data patterns but cannot interpret them within the context of human behavior.
From Statistics: CSS inherits inferential discipline. Does the model fit the data well? Do results generalize? Without statistical discipline, complex models can conceal basic inferential problems that a classical statistician would immediately recognize.
From Computer Science: CSS inherits processing tools — how to collect and clean data at scale, how to train machine learning models, how to design computational simulations. Without this technical capacity, social researchers are limited to datasets that humans can process manually.
PART 2: Four Technical Pillars of CSS
2.1 Social Network Analysis — Making Hidden Structure Visible
Social Network Analysis (SNA) studies social entities as nodes in a network and the relationships between them as edges. SNA’s origins trace to Jacob Moreno’s sociometric work in the 1930s, but large-scale application became feasible only when computational power could handle networks of millions of nodes.
Core measurement quantities in SNA: degree centrality (number of direct connections), betweenness centrality (frequency with which a node lies on the shortest path between two others), and closeness centrality (a node’s average distance to all other nodes). These are not merely descriptive — they are theoretically meaningful variables about influence, information power, and vulnerability within the system.
A canonical application in political science: Cranmer and Desmarais (2011) in Journal of Conflict Resolution used Exponential Random Graph Models to test whether alliance behavior is driven by dyadic characteristics or by higher-order network effects — a question traditional regression analysis cannot answer because the independence assumption is violated when the unit of analysis is a dyadic relationship within a network.
2.2 Text Analysis and NLP — Reading Millions of Documents
Natural Language Processing (NLP) transforms unstructured text — politician speeches, social media comments, court rulings, news articles — into quantifiable data, opening entire worlds of research that previously required manually reading enormous document volumes.
- Topic Modeling: Algorithms such as LDA classify large document corpora into latent topics without manual classification. Typical application: analyzing the evolution of policy agendas in congressional speeches over decades.
- Sentiment Analysis: Identifies emotional valence — positive, negative, neutral — to measure real-time public sentiment toward policies or leaders.
- Large Language Models in Research: GPT-4, Claude, and comparable models serve as analytic instruments — classifying text by pre-specified theoretical criteria, extracting structured information from unstructured text, and enabling large-scale coding.
2.3 Agent-Based Modeling — Simulating Complex Social Systems
Agent-Based Modeling (ABM) is a computational method in which the researcher designs agents with specified characteristics and behavioral rules, places them in a structured environment, and observes the system-level social patterns that emerge from their interactions.
ABM’s distinctive strength is studying emergent properties — system-level patterns that cannot be predicted directly from individual agent characteristics. Axelrod (1997) in The Complexity of Cooperation used ABM to demonstrate that cooperative behavior can evolve in populations of entirely self-interested agents through simple mechanisms like Tit-for-Tat — a result with profound implications for the theory of collective action and international relations.
2.4 Big Data Analysis — Scale as an Analytic Instrument
Boyd and Crawford (2012) characterize big data by three Vs: Volume, Velocity of generation, and Variety of types. In the CSS context, a fourth attribute is frequently more important: Veracity — the accuracy and representativeness of the data.
Common large data sources: mobile phone call detail records providing population-scale movement and network data; social media data (Twitter/X, Reddit, Facebook) for opinion and information diffusion; administrative data (health records, tax records) with near-complete population coverage; and satellite and remote sensing data for economic activity and land-use change.
PART 3: Implementation Workflow — From Question to Interpretation
3.1 Data Collection: Web Scraping and APIs
Web scraping automates data collection from websites by parsing HTML structure. In Python, BeautifulSoup and Scrapy are standard tools. Important legal note: many websites prohibit scraping in their terms of service, and large-scale scraping without a fair-use policy can impose server burden.
APIs (Application Programming Interfaces) represent a more structured and generally preferable alternative: data providers offer documented endpoints with explicit access rules and often explicit approval of academic use. However, recent platform policy changes have created new challenges for research reproducibility.
3.2 Pre-processing, Analysis, and Theory-Grounded Interpretation
In a typical CSS workflow, data pre-processing consumes sixty to eighty percent of total research time. Raw web data is typically missing values, inconsistent, and biased. Critical pre-processing steps: deduplication and bot detection (particularly for social media data), missing value handling, format normalization, and representativeness validation.
The interpretation phase — situating results within social theory — is what distinguishes CSS from pure data analysis. A topic model on five million tweets is not by itself social science. It becomes social science when the researcher places the discovered topics in dialogue with theories of media agenda-setting, ideological diffusion, or political polarization.
PART 4: EEAT Challenges — Ethics, Bias, and Representativeness
4.1 Algorithmic Bias — The Problem That Cannot Be Sidestepped
Algorithmic bias occurs when a machine learning model replicates and amplifies biases in its training data. Algorithms are not intentionally biased — they reflect the biases in the data on which they were trained, and that data reflects the biases of society and the data collection process.
The canonical example: recidivism prediction models used in the US justice system (such as COMPAS) were demonstrated to incorrectly predict higher recidivism rates for Black Americans than for white Americans, even controlling for other relevant variables — because historical arrest and conviction data reflects unequal policing across communities.
In social research contexts, algorithmic bias manifests subtly: models trained primarily on English text perform poorly on other languages; models trained on Twitter do not represent the population that does not use Twitter. Salganik (2018) in Bit by Bit: Social Research in the Digital Age calls this the problem of ‘data that are available but not representative’ — one of the largest threats to the external validity of CSS research.
4.2 The Big Data Paradox — Why Deep Data Still Matters
Lazer and Sayeed (2015), in the ‘Parable of Google Flu,’ illustrated that Google’s Big Data model predicting flu from user searches failed substantially in forecasting because it captured a surface correlation signal without understanding the underlying causal mechanism. CSS at its best is not CSS that replaces interviews with Twitter — it is CSS that uses large data to surface patterns requiring explanation, then uses deep data to understand the mechanisms producing those patterns.
4.3 Research Ethics in the Digital Era
When a researcher uses publicly available Twitter data, do users consent to their public tweets becoming research data? Zimmer (2010) argued that technical publicity does not equate to informed consent — people who post public tweets do not necessarily expect those tweets to be analyzed and published in academic journals.
Good practice principles: anonymize data even when the source is public; minimize data collection to what is genuinely necessary; consider re-identification risk after anonymization; be transparent about data sources and collection procedures so readers and reviewers can evaluate representativeness.
Conclusion and Recommended References
CSS represents a genuine expansion of cognitive capacity in social science. The best CSS researchers are not those who know the most techniques, but those who can ask theoretically meaningful questions, know when big data is the right tool and when deeper data is needed, and have the methodological discipline to understand that a model that fits the data is not the same as understanding the mechanism.
Recommended references:
Lazer, D., et al. (2009). Computational social science. Science, 323(5915), 721–723.
Boyd, D., & Crawford, K. (2012). Critical questions for big data. Information, Communication & Society, 15(5), 662–679.
Salganik, M. J. (2018). Bit by bit: Social research in the digital age. Princeton University Press.
Axelrod, R. (1997). The complexity of cooperation. Princeton University Press.
Cranmer, S. J., & Desmarais, B. A. (2011). Inferential network analysis with exponential random graph models. Political Analysis, 19(1), 66–86.
Zimmer, M. (2010). But the data is already public. Ethics and Information Technology, 12(4), 313–325.
◉ 0 Thảo luận Khoa học