
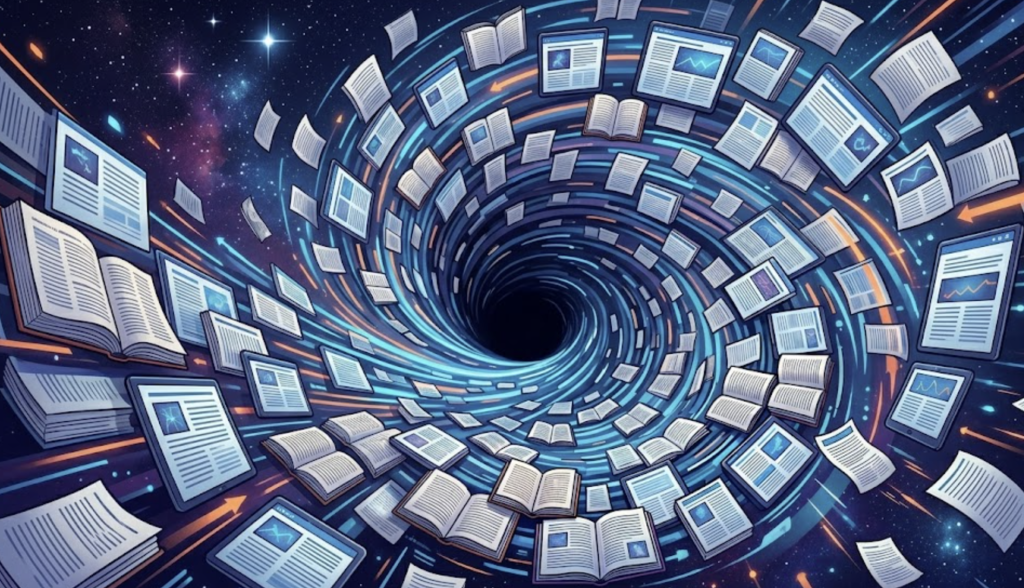
There is a particular kind of exhaustion that only researchers know. It is not the exhaustion of physical labor, and it is not even the exhaustion of sustained concentration. It is something subtler: the exhaustion of trying to hold too much at once, of watching the coherent picture you were building slowly dissolve as each new piece of information pushes an earlier one out of reach.
Most researchers who have attempted a thorough literature review describe the same arc. The first twenty papers feel manageable — you are building a mental map, finding the key names, tracing the debates. By fifty papers, the map starts to blur. By one hundred, you are reading the same argument in its fourth iteration and can no longer clearly remember which version you found most convincing, or who first made it, or what the counter-evidence was. By two hundred papers, you have a folder full of PDFs and a growing suspicion that you are no longer capable of synthesizing them honestly.
This is not a failure of intelligence. It is a failure of architecture. The human brain was designed for depth, not for breadth at scale. Working memory holds roughly four to seven units of information at once. Long-term memory is powerful but reconstructive — which means it introduces distortions every time you reach into it. We are magnificent at understanding one thing deeply. We are genuinely poor at holding five hundred things simultaneously and seeing how they all fit together.
The problem is not a shortage of information. The problem is that human cognition was never designed to process information at the scale that modern scholarship demands.
Systematic Literature Review: The Gold Standard Nobody Actually Completes
Systematic Literature Review — SLR — is the methodology that academic medicine, public health, and increasingly every empirical discipline holds up as the correct way to synthesize evidence. The logic is compelling: rather than cherry-picking the studies that support your prior view, you define your search strategy in advance, cast a wide net across multiple databases, apply explicit inclusion and exclusion criteria, extract data using a standardized template, and assess the quality of each study using validated tools. You document every decision. The process is reproducible. The result is a body of evidence, not a body of opinion.
The problem is that a realistic SLR typically begins with somewhere between two thousand and eight thousand raw search results. After title and abstract screening, that might reduce to four hundred. After full-text review, perhaps sixty to one hundred studies remain for data extraction. Each of those sixty studies contains dense methodological detail that must be captured accurately and consistently. A research team at the University of Oxford found that the average time to complete a systematic review, from protocol development to published manuscript, is sixty-seven weeks. Many reviews are never completed at all. They stall somewhere between the second database export and the full-text screening pile that nobody can quite face.
The bottleneck is not intellectual. It is mechanical. The sheer volume of text that must be processed, categorized, and compared exceeds what any individual or small team can sustain without either cutting corners or burning out entirely.
What Claude 3.5 Sonnet and OpenClaw Gateway Actually Do
When people first hear that AI can help with literature reviews, they often imagine a chatbot that summarizes papers on demand — useful, perhaps, but not fundamentally different from a very fast reading assistant. What Claude 3.5 Sonnet combined with OpenClaw Gateway enables is something architecturally different.
OpenClaw Gateway functions as an orchestration layer. It manages the batched submission of documents, maintains consistent prompt structure across hundreds of separate processing calls, and collects structured outputs into a unified dataset. Claude 3.5 Sonnet brings a context window of up to 200,000 tokens — large enough to hold an entire research paper, including tables and supplementary material, without truncation. The combination means you can define a fixed set of extraction questions, apply them to every paper in your corpus with absolute consistency, and receive back structured data that can go directly into your analysis environment.
The consistency is the part that matters most. When a human reviewer extracts data from the forty-seventh paper in a stack, their performance is meaningfully different from their performance on the third paper. Attention degrades. The implicit standards for what counts as a positive finding drift. The criteria for ‘unclear risk of bias’ blur. These are not character failures — they are documented features of human cognitive performance under sustained, repetitive demand. AI does not have this problem. The fiftieth extraction is executed with identical precision to the first.
The Hallucination Problem, and the Principle That Solves It
Any serious discussion of using AI for academic research has to confront hallucination directly. Large language models sometimes generate confident-sounding content that is factually incorrect — invented citations, fabricated statistics, conclusions that no actual study ever reached. In casual use this is annoying. In academic research it is disqualifying.
The principle that makes AI genuinely safe for data extraction is simpler than most people expect: never ask AI what it knows. Only ask AI what it can see in the text you have given it.
The distinction is fundamental. When you ask Claude ‘what does the literature say about the effect of intervention X on outcome Y’, you are asking it to draw on its training data — a vast, partially reliable, and unverifiable internal representation of the world. That is where hallucination lives. But when you ask Claude ‘in the methods section of this paper, what instrument did the authors use to measure outcome Y’ — and you have provided the full text of that paper in the same context window — you are not asking it to recall anything. You are asking it to read and report. The text is right there. The answer is either in it or it is not, and Claude can tell you which.
In practice this means the document always precedes the question. You never ask about a paper without first loading its full text into the session. The prompt template is structured so that every question is a retrieval task with a bounded domain — the answer must come from this text, and if the text does not contain the answer, the model should say so and flag it for human review. OpenClaw Gateway enforces this structure systematically across every document in the batch.
Do not ask AI what it knows. Ask AI what it finds in the document you have given it. That single distinction separates trustworthy extraction from hallucination.
The Practical Workflow: From Five Thousand Results to Publishable Insight
The workflow begins where it always has: with a well-constructed search strategy. This is not something AI can do for you, and you should be cautious of any tool that claims otherwise. Defining your PICO or SPIDER framework, selecting the appropriate databases, constructing Boolean search strings that are sensitive enough without being unmanageable — these require domain expertise and methodological training. AI is not a substitute for knowing your field.
Once you have your raw search results exported as RIS or CSV files, AI begins to earn its place. Title and abstract screening is the first application. You build a prompt that encodes your inclusion and exclusion criteria precisely, pass each title-abstract pair through Claude via the OpenClaw Gateway, and receive back a binary decision with a brief rationale. The recommendation is to run this in parallel with at least one human screener and calculate inter-rater reliability — Cohen’s Kappa between experienced human reviewers and Claude 3.5 Sonnet at this stage typically falls between 0.75 and 0.85, which is within the range considered acceptable for systematic review methodology.
After full-text retrieval, the data extraction phase begins. This is where structured prompt templates deliver their most significant value. Each paper receives the same set of extraction questions in the same order: study design, sample size, population criteria, intervention description, comparison condition, outcome measures and instruments, primary results with effect sizes and confidence intervals, author-identified limitations, and declared conflicts of interest. Claude returns a structured JSON object. OpenClaw writes it to your master spreadsheet. Your job at this stage is verification — reviewing a random sample of extractions against the source documents, and handling every case the model flagged as ambiguous or incomplete.
The result is a clean, structured dataset from two hundred papers that took three to four working days rather than three to four months. Not because AI did the thinking. Because AI handled the mechanical volume, allowing the researcher to invest their attention where it is genuinely irreplaceable.
What AI Cannot Replace
This should be said plainly: the value of this approach depends entirely on the researcher understanding its limits. Claude 3.5 Sonnet is exceptionally good at processing large volumes of text consistently, at never becoming fatigued or bored, at returning structured output in exactly the format you specify. It is genuinely poor at epistemological judgment.
Deciding which research questions matter is a human responsibility. Designing inclusion criteria that reflect genuine methodological quality rather than arbitrary convenience requires domain expertise. Risk of bias assessment using tools like the Cochrane Risk of Bias 2 tool or the GRADE framework involves nuanced judgment calls that cannot yet be safely automated. And interpreting what the synthesized evidence means for practice, policy, or future research — contextualizing it within the theoretical debates of your field, understanding what is missing from the evidence base, knowing which findings are robust and which are artifacts of study design — remains irreducibly human work.
What this combination of tools makes possible is not the elimination of the researcher. It is the expansion of what a single researcher, or a small team, can honestly and rigorously synthesize. That is a meaningful shift. The knowledge black hole does not close entirely. But it gets substantially smaller.
◉ 0 Thảo luận Khoa học